Cost & Estimation
13 min read•Ajay Chaudhary
AI Development Cost in 2026: A Practical Pricing Guide
Read Article
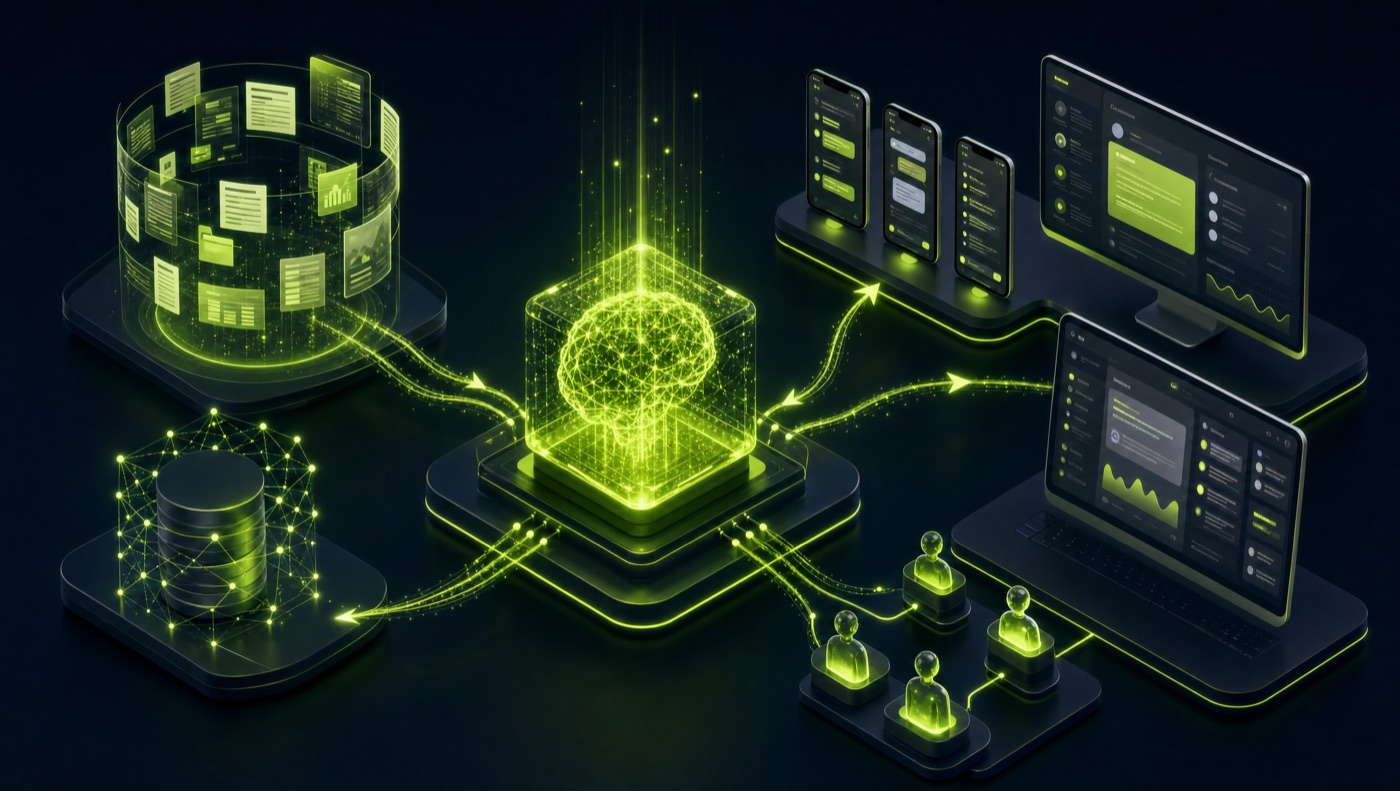
We build retrieval-augmented generation systems that ground every AI answer in your verified documents, eliminating hallucination risk and keeping responses current as your knowledge base evolves.
Trusted by conglomerates, enterprises and startups alike
Quick answer: RAG (retrieval-augmented generation) means a model looks up your actual documents before it answers, instead of relying only on what it learned during training. Generic LLM answers are only as good as their training data, which is frozen and can't cite sources. RAG changes that by grounding every answer in your live, verified knowledge base, for clients across United States, United Kingdom, Australia, United Arab Emirates, Canada, and India, including AI development services in California and AI development company in Dubai.
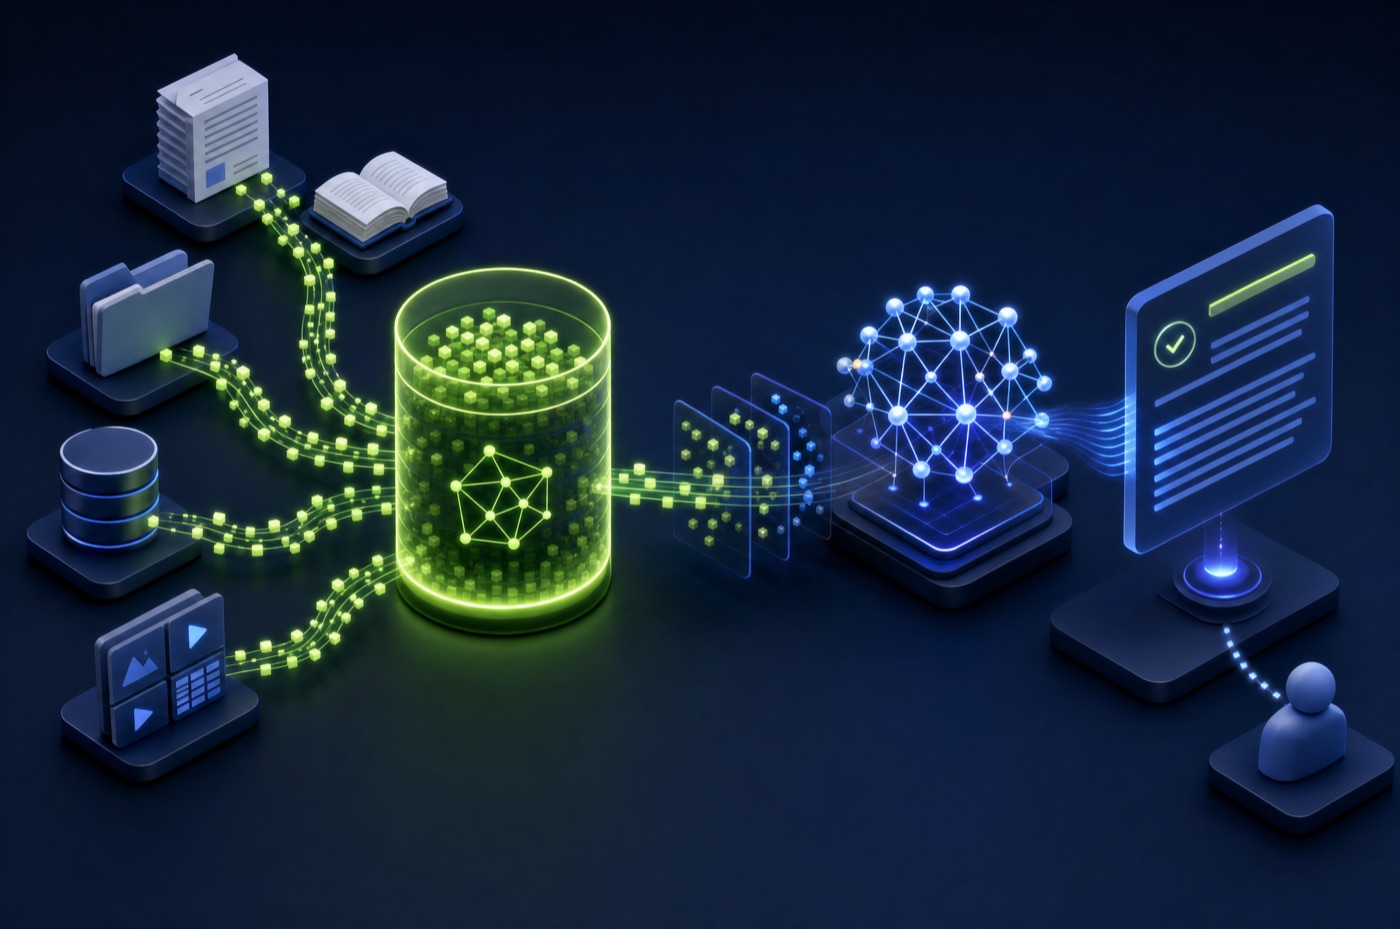
Answers grounded in your verified knowledge base, eliminating hallucination risk that plain LLM prompting can't solve.
Production-grade vector database architecture, built by our machine learning development services team, that scales to millions of documents without latency degradation.
Automated pipelines that keep your RAG system current as source documents change, not stuck on a training-time snapshot.
Every answer traceable back to its source document, reviewed against your industry's specific compliance requirements for regulated sectors.
Retrieval spanning documents, databases, and APIs in a single grounded response, connected through our AI integration services team rather than siloed lookups.
Real products where retrieval, not a static prompt, decides what the AI shows someone.
Built the retrieval layer behind an AI keyboard that surfaces a creator's saved captions, hooks, and templates the moment they're needed, replacing a manual scroll through old posts.
 Verified Client Review
“They cleared all my doubts and turned my idea into a powerful app.”
CEO, PlayHuman
 Verified Client Review
“The AI-powered fitness platform Apptechies developed integrates personalized workout plans, nutrition tracking, and real-time progress monitoring in one beautiful app. Their technical execution has been exceptional.”
Owner, Ultravoom
 Verified Client Review
“Flawless execution, smooth communication, and on-time delivery.”
Owner, GenieChat
Explore Services
RAG Development
Strategic advisory identifying where retrieval-augmented generation delivers real accuracy gains over plain LLM prompting.
Data Security & Compliance Standards
“Apptechies has been a reliable engineering partner on our link-management platform, working across web, iOS, and Android with a level of scalability and reliability that’s simply phenomenal. They are world-class engineers.”
“The MSK performance platform Apptechies built has changed how our clinicians track patient outcomes. The data-driven insights have significantly improved rehabilitation decisions, and the team understood our clinical domain deeply from day one.”
“Movesy has completely transformed the moving and delivery industry thanks to Apptechies. The GPS tracking, dynamic pricing, and route optimisation they built has made our operations incredibly efficient.”
Discover our full spectrum of specialized AI service lines — from foundational strategy and custom model training to intelligent autonomous agents.
Common questions about working with our RAG engineering team. Can't find yours? Ask us directly.
It covers a knowledge base audit, chunking and indexing strategy, embedding model selection, vector database setup, retrieval ranking tuning, and integration into wherever people will actually ask questions. Most clients start with a single knowledge source rather than indexing everything at once.
Retrieval-augmented generation grounds AI answers in your verified documents rather than relying purely on what a language model learned during training, dramatically reducing hallucination and keeping answers current as your knowledge base changes.
The main cost drivers are how much content needs structuring before it can be indexed, whether you need a single knowledge source or multi-source retrieval across documents, databases, and APIs, and how deep the integration into your existing tools needs to go. We size this after a knowledge base audit rather than quoting a number blind.
Fine-tuning bakes knowledge into model weights, which goes stale and is expensive to update. RAG retrieves from a live, updatable knowledge base at answer time, so updating a document updates every future answer instantly.
A focused RAG proof-of-concept typically takes 4-8 weeks. Enterprise-scale deployment with multi-source retrieval and full integration usually takes 12-18 weeks, scoped after a knowledge base audit.
We start with a knowledge base audit and use-case scoping, then chunking and indexing strategy, then embedding model and vector database selection, then retrieval and generation integration, then hallucination and accuracy testing, and finally production deployment with monitoring.
We enforce strict source grounding, confidence thresholds that trigger human escalation for low-confidence answers, and mandatory citation display so every answer is traceable and verifiable.
Yes. We build multi-source RAG architectures that retrieve across documents, databases, and APIs in a single grounded response, rather than requiring separate lookups.
It depends on how your data changes and how the answer needs to be produced. If your knowledge base updates often and answers need to cite it accurately, RAG usually wins. If you need a model that consistently reasons in your domain's own terminology, fine-tuning fits better. A fully custom model is reserved for cases where neither approach solves the problem.
We handle the full data structuring pipeline, chunking strategy, metadata tagging, and indexing, as a core part of every RAG engagement, not something we expect you to prepare in advance.
Yes. Our AI integration services team embeds RAG-grounded answers directly into the support, search, and internal tools your team already uses, rather than shipping a separate standalone app.
We work within your existing access controls and only index what you authorise, with encryption and audit trails covering how documents move through the retrieval pipeline.
Yes. If you would rather embed engineers into your own team than commission a fixed-scope build, you can hire dedicated AI developers who work under your direction on your existing knowledge base and stack.
Absolutely. Full IP assignment is standard on every engagement. You own the code, indexing pipelines, embeddings, and all associated documentation outright.
Knowledge bases keep changing, so we offer structured monitoring and re-indexing retainers to keep retrieval accurate after launch, rather than leaving the system to drift out of date.
We work with clients across United States, United Kingdom, Australia, United Arab Emirates, Canada, and India, from early-stage startups through enterprise teams. Engagement scope is shaped by the project itself, not by where you are based.
Book a free consultation with our senior RAG engineers.